ADH overview
Arenadata Hyperwave (ADH) is a universal hybrid platform based on open-source components and proprietary developments designed for storing, processing, and analyzing structured, semi-structured, and unstructured data at scale.
The platform supports multiple deployment and data management paradigms and provides a flexible set of tools for implementing Lakehouse architectures and cost-effective Data Lake storage. It enables hybrid deployments that combine on-premises and cloud infrastructure within a single data platform.
Architectural principles
-
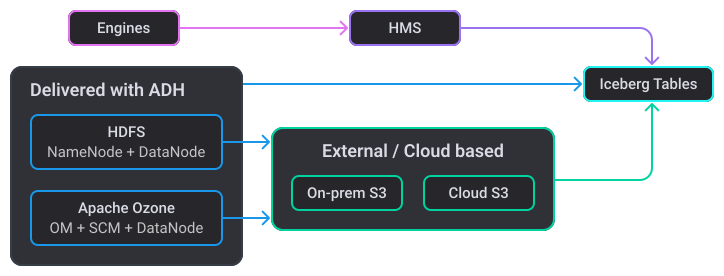
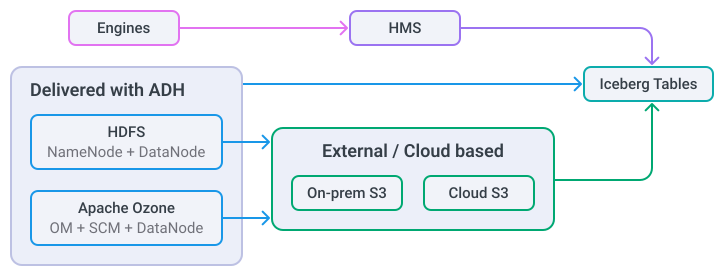
The storage layer can consist of HDFS, Ozone, S3-compatible storage, and external cloud object storage.
-
Data is stored in open formats such as Parquet, ORC, and Avro.
-
Tables can use open table formats such as Apache Iceberg, while metadata can be managed through catalog services such as Apache Hive Metastore.
-
Multiple SQL, batch, and stream processing engines (Impala, Spark, Trino, Flink, and others) can access the same datasets.
-
Compute and storage resources can be separated for elastic scaling or colocated to maximize data locality.
-
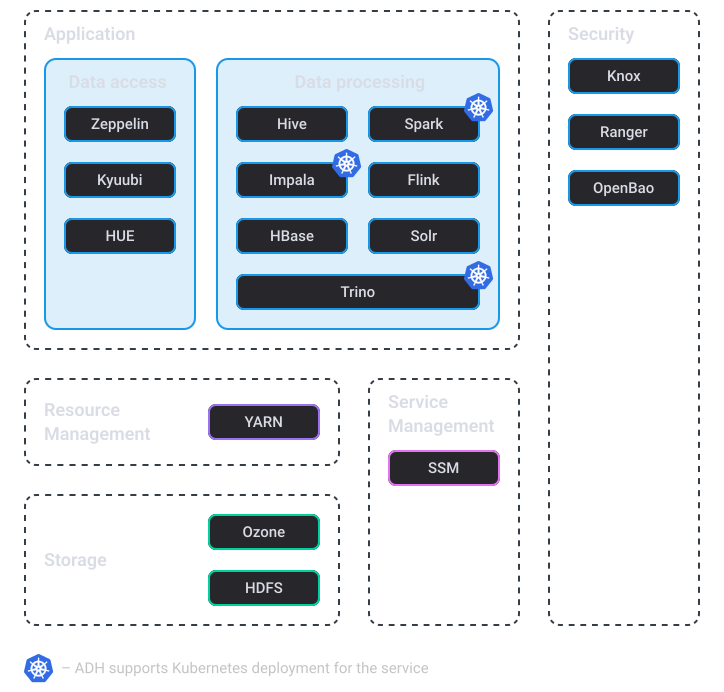
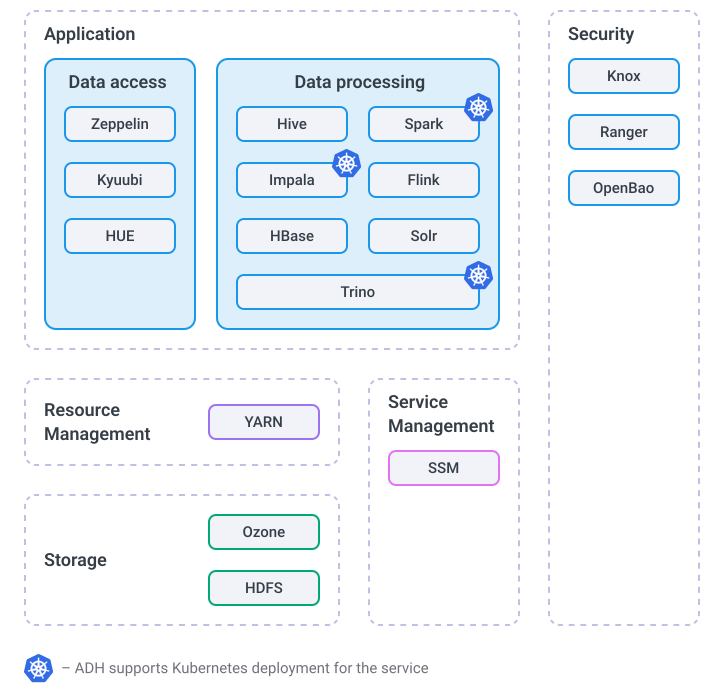
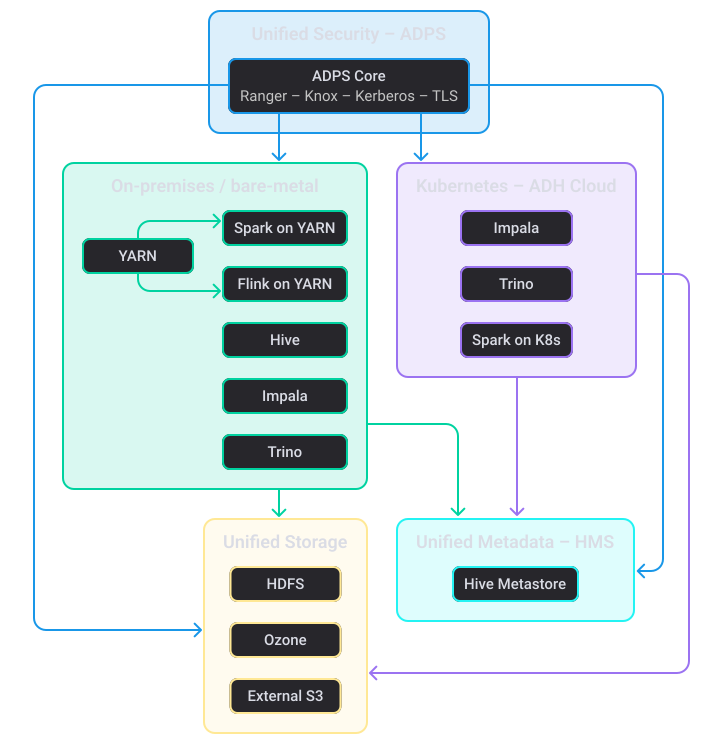
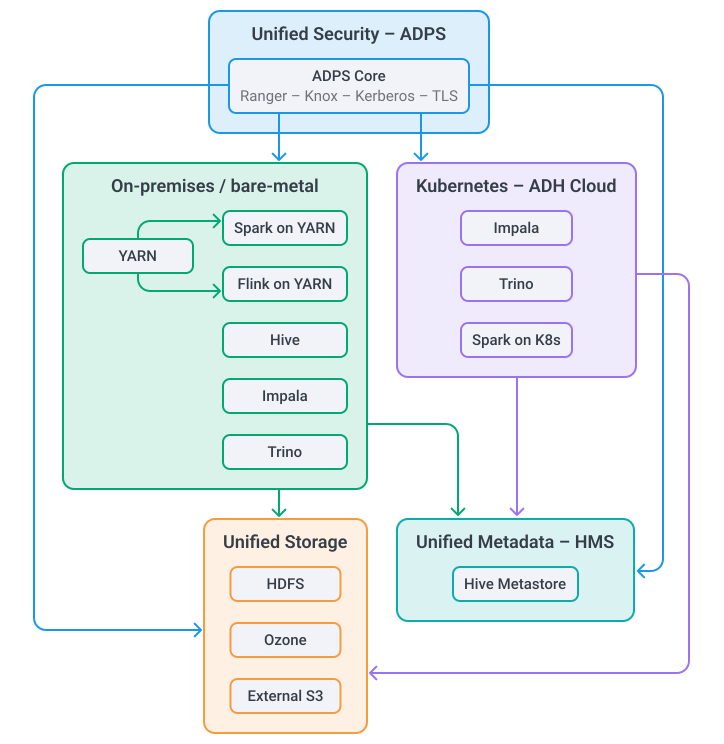
Compute resources can run on-premises, in Kubernetes, or in public cloud environments. Kubernetes deployment is currently available for Spark, Impala, and Trino.
-
Security and governance policies are applied consistently across all platform layers.
Storage layer
The platform allows you to use a single storage system or combine multiple storage services within the same deployment. The storage layer is built as a unified, format-agnostic foundation: it does not impose a single persistence model, but rather provides a logical data plane where multiple physical backends can coexist.
This enables storage federation, allowing hot, warm, and cold data to reside on different storage media and in different locations while remaining accessible through the same SQL and compute engines.
| Storage | Scenario | Key attributes |
|---|---|---|
HDFS |
Large files, intensive batch processing, data locality is important |
Proven on-premises storage layer; supports erasure coding to reduce replication overhead |
Ozone |
Large numbers of small files, object access, S3 compatibility |
HDFS alternative for object-native workloads; native multiprotocol access (S3, OFS, Ozone FS) |
External S3 |
Hybrid cloud, data sharing, backup, disaster recovery |
Data can reside outside the ADH cluster; suitable for archival storage and cross-region replication |
Compute layer
The compute layer in Arenadata Hyperwave is designed as a multi-engine, elastic execution environment that decouples processing logic from physical infrastructure. Rather than binding workloads to a single engine or deployment model, the platform provides a unified compute layer where multiple execution frameworks operate concurrently on the same datasets.
| Capability | Description |
|---|---|
Multi-engine concurrency |
Impala, Spark, Trino, Flink, and other engines can access the same datasets through the unified storage layer. This eliminates data silos and reduces ETL duplication. The same Parquet files or Iceberg tables can be queried interactively, processed in batch, or consumed as streaming sources without format conversion or physical copying |
Compute-storage disaggregation |
Compute clusters can reside on-premises, in Kubernetes, or in public cloud environments, while data persists in HDFS, Ozone, or S3-compatible storage. This enables independent scaling of compute and storage resources. For example, transient Spark clusters can be provisioned for peak workloads without increasing storage capacity |
Hybrid deployment |
The platform supports both traditional standalone clusters (YARN-based or bare-metal) and cloud-native Kubernetes orchestration. Latency-sensitive services such as Impala can run on dedicated physical nodes, while Spark workloads can be deployed in Kubernetes to benefit from container-based elasticity |
Unified governance and security |
ADPS tools allow enforcing access control, data masking, and audit policies consistently regardless of the execution engine or deployment target. Apache Ranger policies, Kerberos authentication, and encryption in transit apply uniformly across standalone and Kubernetes-based execution environments |
Access layer
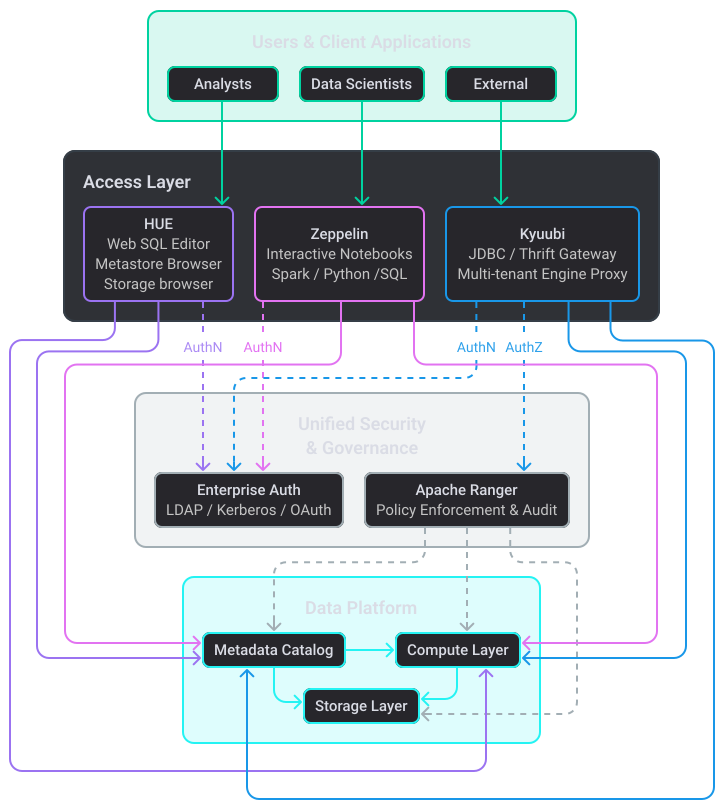
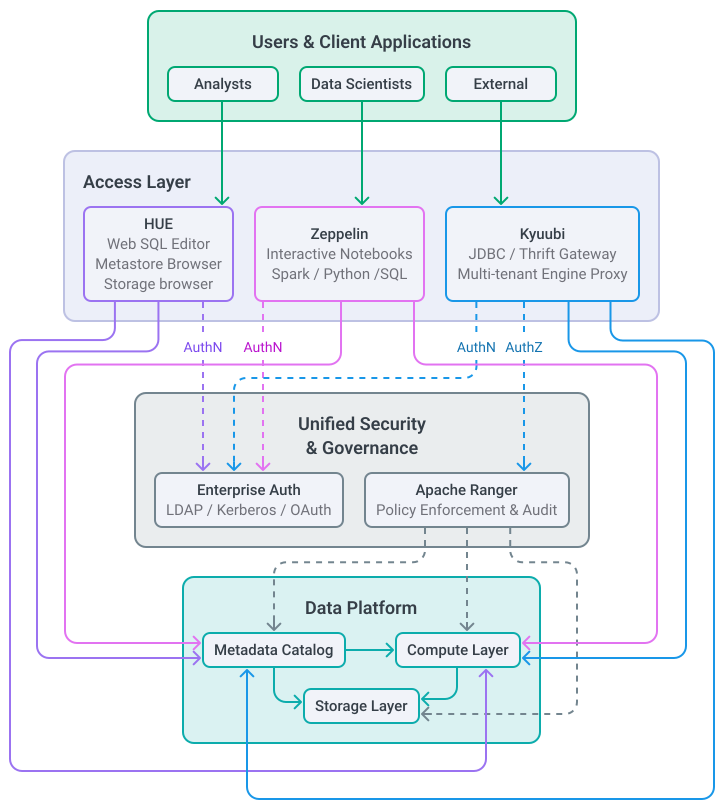
The access layer provides a unified interaction point for all platform users. Rather than exposing raw compute endpoints, it offers secure and user-friendly interfaces that abstract execution engine complexity and allow analysts, data scientists, and application developers to work with the same governed data using tools appropriate for their workflows.
| Capability | Description |
|---|---|
Interactive SQL and data exploration |
Apache HUE provides a web-based SQL editor, metadata browser, and job management interface. Analysts can run ad hoc queries across Impala, Spark SQL, Hive, and Trino, inspect table schemas, and manage jobs through a unified web interface |
Enterprise JDBC/Thrift gateway |
Apache Kyuubi provides a multi-tenant, high-concurrency gateway that exposes Spark and other engines through standard JDBC and Thrift endpoints. BI tools, reporting platforms, and custom applications connect through Kyuubi rather than directly to cluster nodes, providing session isolation, resource fairness, and transparent engine routing |
Collaborative data science notebooks |
Apache Zeppelin provides interactive, multi-language notebooks with native interpreters for Spark, SQL, Python, and R. Data scientists can prototype pipelines, visualize results, and share interactive notebooks while accessing the same Iceberg tables and Parquet datasets as SQL users |
Unified authentication and authorization |
Every entry point, including Hue sessions, Kyuubi JDBC connections, and Zeppelin notebooks, integrates with enterprise identity systems such as LDAP, Kerberos, SAML, and OAuth. Authorization policies are enforced centrally through Apache Ranger, including row-level filtering, column masking, and audit logging |